TL;DR. Newa is a voice assistant for Nepali and Newari (नेपाल भाषा) that runs entirely on one Mac Studio, with no cloud API. You talk to it; it answers out loud in four modes: it translates, chats, teaches a short Newari lesson and reads the news. Under it are three models we trained. Our translation adapter lifts Gemma-4-E4B from 21.96 to 55.91 chrF++ (Nepali → Newari) and from 12.85 to 43.04 on spoken Newari. Our 33M-parameter recognizer reads Newari at 17.95% CER. Chat replies start speaking in 1.0–1.6 s. The main limit: no Newari speaker has rated the output yet, and single words are its weakest point.
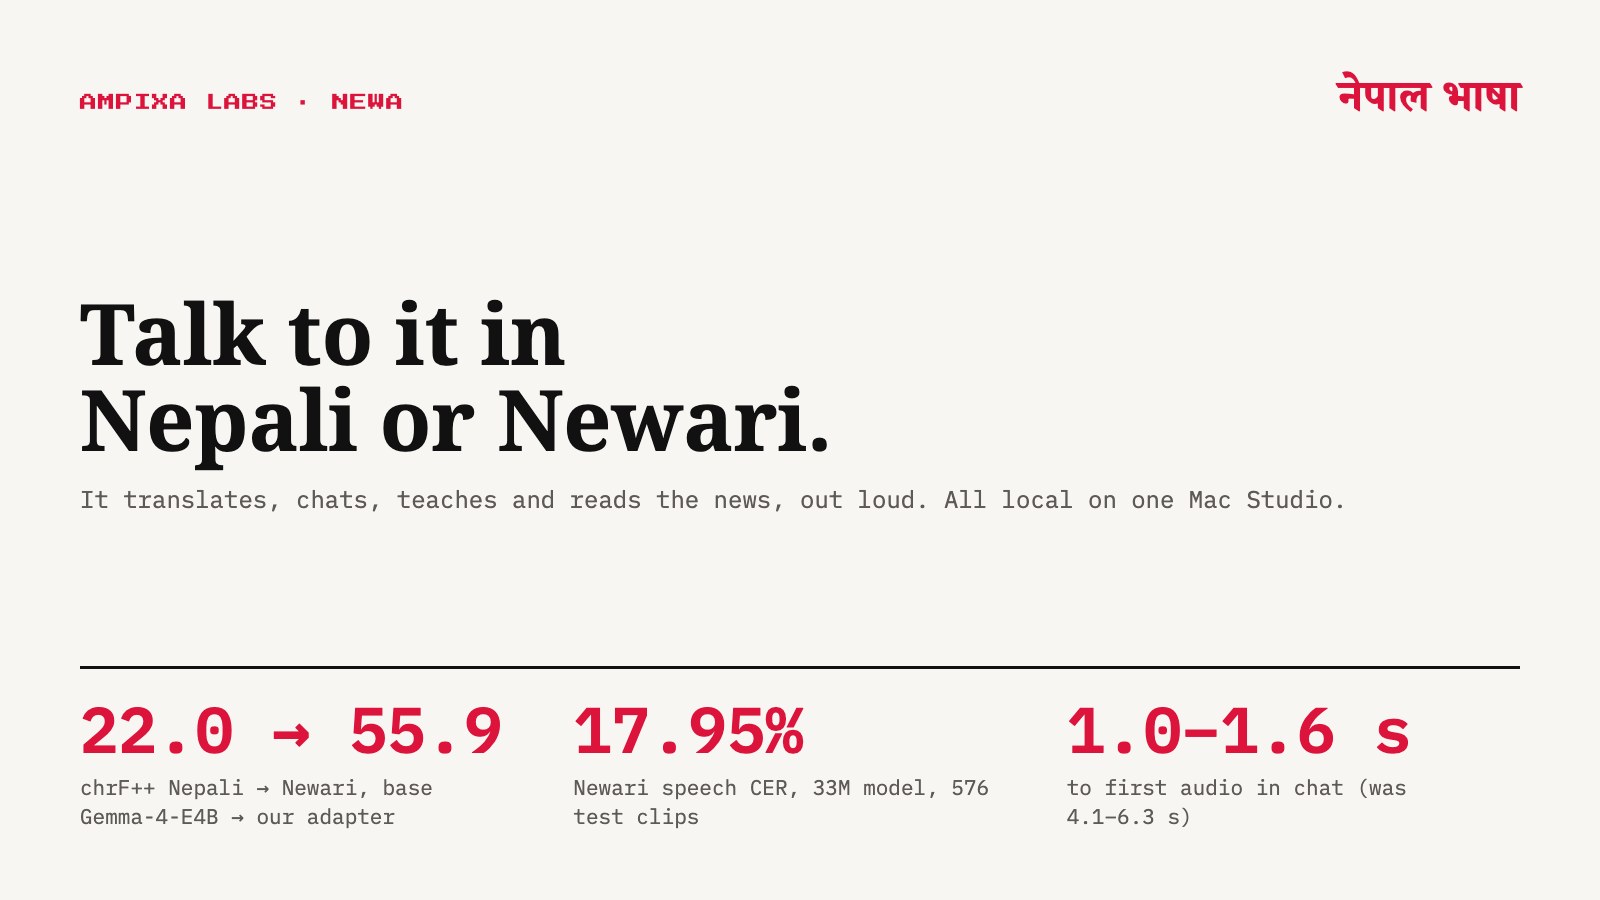
Our adapter takes Nepali → Newari translation from 22.0 to 55.9 chrF++, and the whole loop runs locally.
What does it do?
You tap the orb and speak. It works out which language you spoke, then which of four things you asked for. The reel below was filmed on a phone pointed at the screen: translation first, then chat.
Two minutes of unedited output from the machine, translate mode then chat mode.
| Mode | You say | It does |
|---|---|---|
| Translate | "म घर जान्छु" (I am going home) | says जि छेँ वनि in a Newari voice, and back the other way |
| Chat | a question, in Nepali or Newari | answers in your language; asked "how do I say X in Newari", it answers in Nepali first, then says the Newari |
| Teach | "मलाई नेवारी सिकाउनुहोस्" (teach me Newari) | a six-phrase lesson: it explains in Nepali, says the phrase in Newari, listens to you repeat and scores the try |
| News | "आजको समाचार" (today's news) | reads a three-item bulletin from five Nepali news feeds, with the sources linked |
Four modes behind one microphone; the mode is picked from what you said, not from a menu.
How is it built?
One loop on one machine: detect the language, transcribe, route the request, write or look up the answer, translate, speak. The recognizers, the translation adapter and the voice are ours.
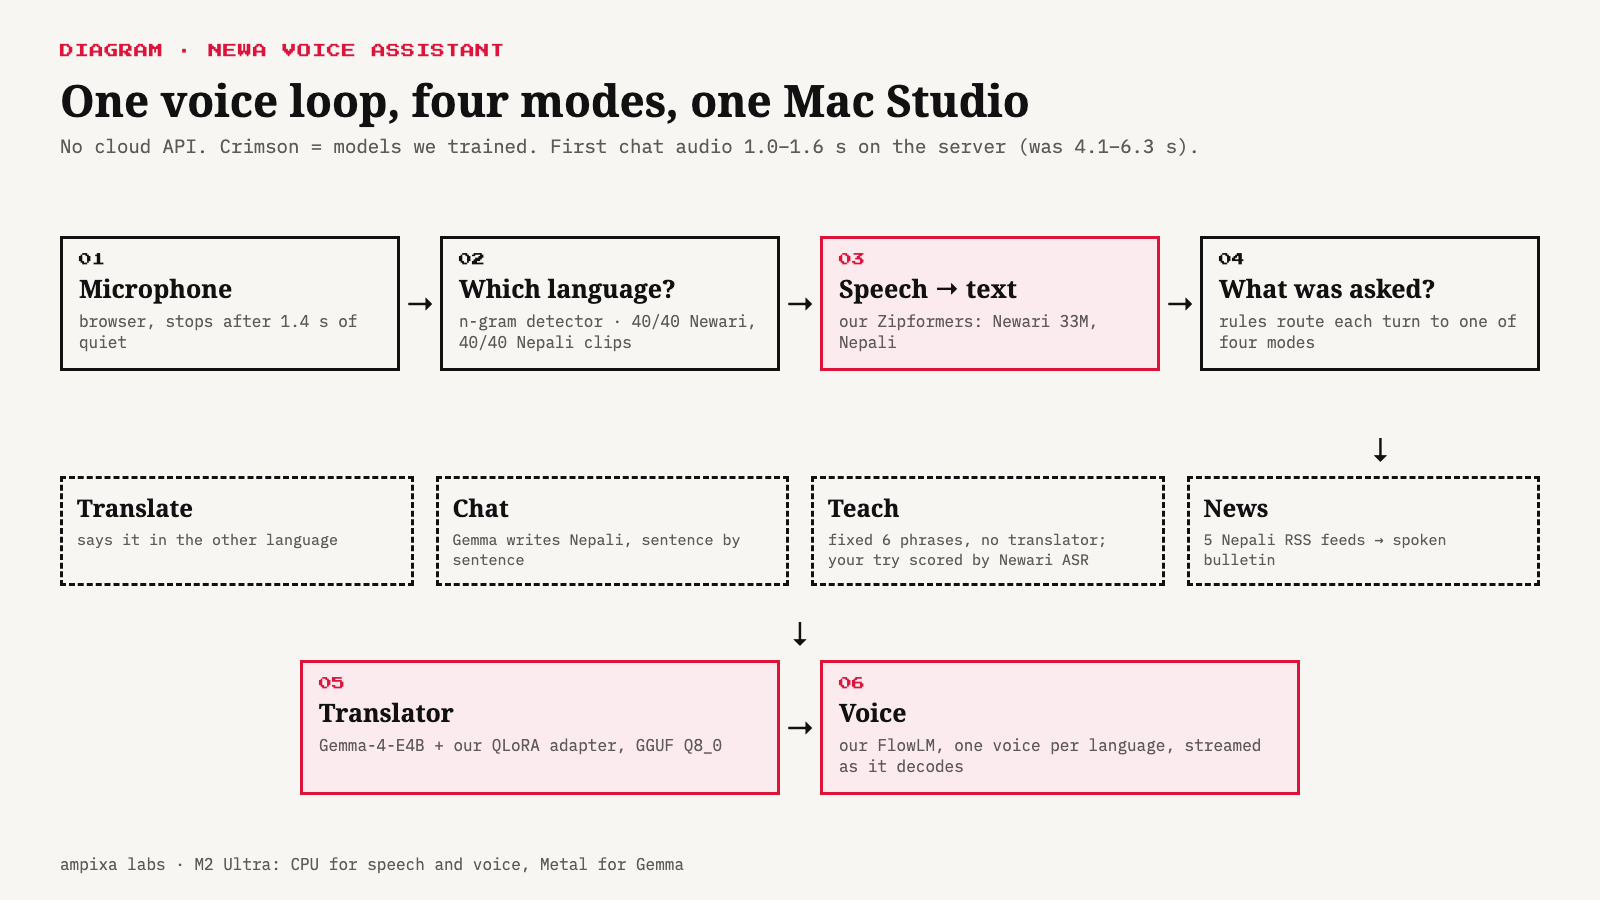
Diagram. Every request runs through the same detector, recognizer and voice; only the middle step changes per mode.
- Which language? A character n-gram classifier (naive Bayes over 1–4-grams) trained on 38,349 sentences per language.
- Speech → text. Newari: our 33M-parameter Zipformer trained on 37 Nepal languages, exported to ONNX with the Newari language embedding baked in. Nepali: a separate Zipformer at 17.78% CER on FLEURS Nepali, against 25.19% for the 37-language model.
- Translator. Gemma-4-E4B with our QLoRA adapter (r = 32), merged and served as GGUF Q8_0 by llama.cpp. Training text: 25.9k real Newari sentences (textbooks, Nwacha Muna transcripts, Wikipedia), back-translated to Nepali and used in both directions. The Q8_0 export scores within 0.5 chrF++ of the PyTorch model.
- The brain for chat and news is the same Gemma, so the whole assistant needs one language model.
- Voice. Our FlowLM text-to-speech, one speaker per language, streamed packet by packet as it decodes.
How good is each part?
The adapter more than doubles every translation score we measured. The recognizer is close to the best published Newari model on CER and better on WER.
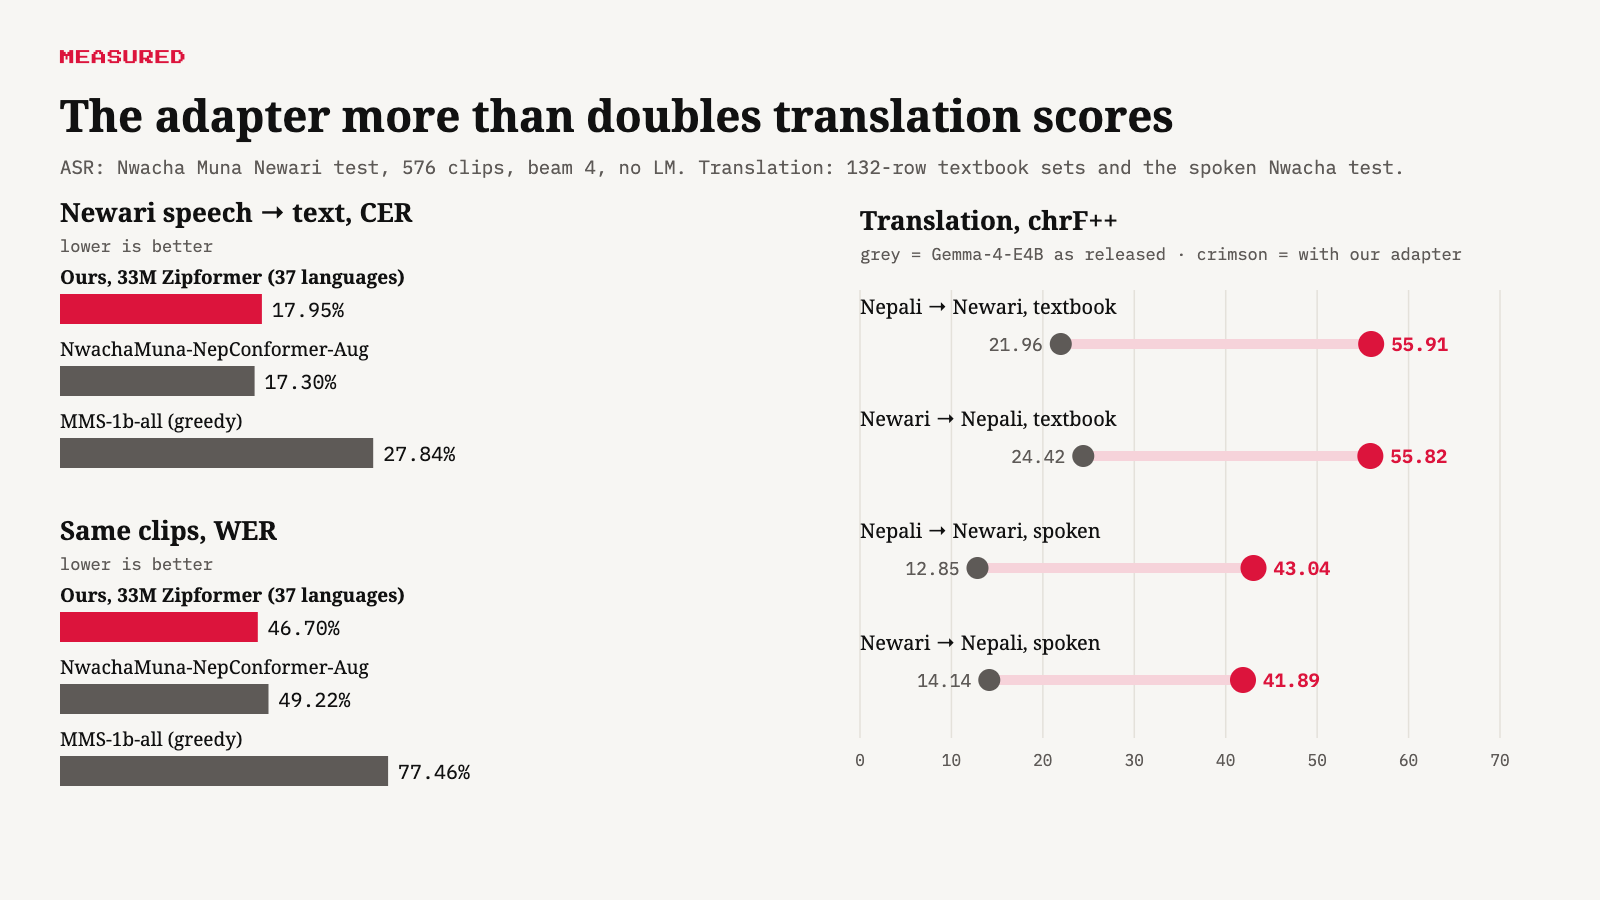
Grey is the released model, crimson is ours. Translation gains hold on spoken Newari, though the absolute scores there are lower (41.89–43.04).
| Newari test (576 clips, beam 4, no LM) | CER | WER |
|---|---|---|
| Ours, 33M Zipformer (37 languages) | 17.95% | 46.70% |
| NwachaMuna-NepConformer-Aug | 17.30% | 49.22% |
| MMS-1b-all (greedy) | 27.84% | 77.46% |
NwachaMuna is 0.65 points better on CER; we are 2.52 points better on WER. We ran all three on the same clips.
| Translation, chrF++ | Gemma-4-E4B | With our adapter |
|---|---|---|
| Nepali → Newari, textbook (132 rows) | 21.96 | 55.91 |
| Newari → Nepali, textbook (132 rows) | 24.42 | 55.82 |
| Nepali → Newari, spoken (Nwacha test) | 12.85 | 43.04 |
| Newari → Nepali, spoken (Nwacha test) | 14.14 | 41.89 |
chrF++ is a character n-gram F-score against a reference translation; 100 means identical.
Where this sits
The closest public work is NwachaMuna, a Newari speech corpus and Conformer recognizer; we compare against it above on its own test set. MMS covers Newari recognition but scores much lower on this set. Kura, our Nepali phone agent, is the sibling project. We know of no other Newari voice assistant to compare against end to end.
What is next?
A Newari speaker reviewing 100 real conversations, conversational training pairs for the translator (short questions are its weakest point), and a number reader for the Newari voice.