Four seconds of a voice. Nepali in that voice.
Eka is our Nepali fine-tune of Audio8-TTS-Preview-0.1b. Give it a short recording of someone speaking and some Nepali text, and it reads the text in that voice. The release checkpoint is eka-ft-v7.
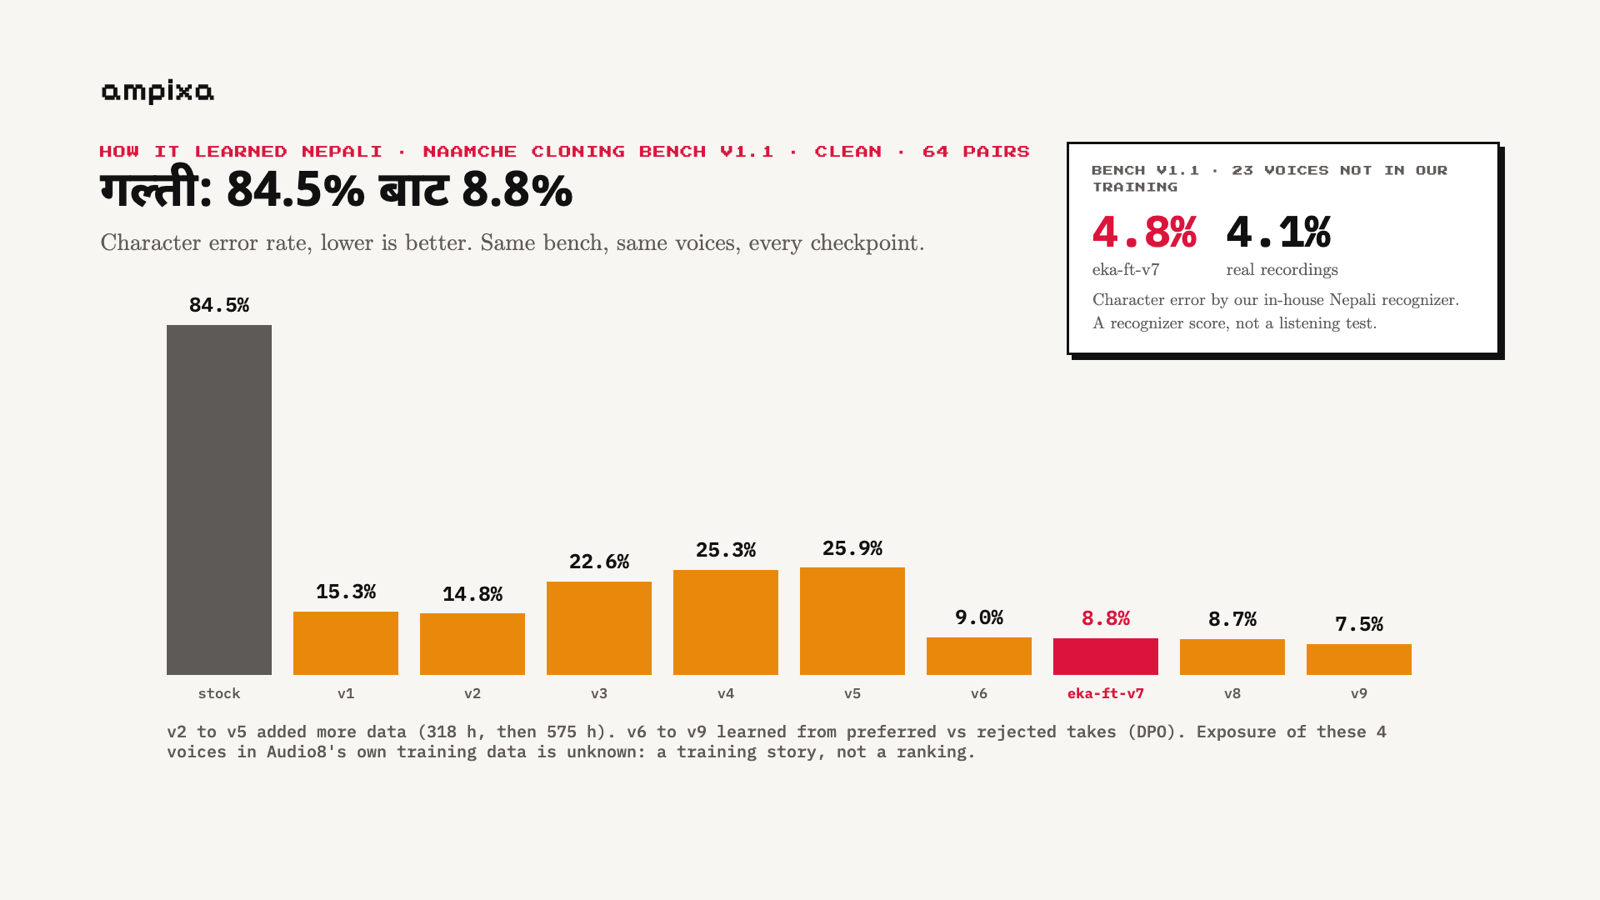
More data did not fix the words. Preference training did.
Stock Audio8 gets 84.5% of characters wrong in Nepali on the Naamche cloning bench. We trained it nine times and kept every checkpoint, released as eka-ft-v1 to v9. Going from 318.8 to 575 hours of supervised data left the error rate flat. Then the model generated six takes per prompt, a recognizer and a speaker judge scored them, and preference training (DPO) pushed it toward the best take.
On 23 voices outside our training, eka-ft-v7 reaches 4.82% character error; real recordings of the same speakers score 4.14% on the same recognizer.
The smallest generator in the lineup.
The ONNX INT8 export runs on a MacBook's Apple M3 Pro CPU with 4 threads at RTF 1.18 on a 39-second paragraph: a little slower than real time, with no GPU. We do not compare CPU speed with other models, because their CPU numbers come from a different machine.
Generator parameters only; codecs and vocoders are not counted (Eka adds a 130M decoder). VoxCPM2 is its total minus its codec.
| Ekathis release | 170M |
|---|---|
| Chatur v2unreleased | 249M |
| Swarpublic | 337M |
| OmniVoicepublic | 613M |
| VoxCPM2public | 2.31B |
Less Hindi leak than the public models we tested.
Most Nepali text-to-speech starts from a Hindi-trained model, and some Hindi pronunciation can survive fine-tuning. Our Hindi Leak Scorer checks key words for a vowel that moved the Hindi way. Every system read the same 26 sentences in the same 4 voices, scored by the same frozen detector.
Denominator: readings that passed the scorer's word check. A flag is a candidate for a listener, not a confirmed error; the scorer has no blind-listener calibration yet. OmniVoice ran on its stock weights with our inference settings.
| IndicF5public | 60 / 93 |
|---|---|
| VoxCPM2public | 55 / 91 |
| Swarpublic | 36 / 100 |
| OmniVoicepublic | 34 / 104 |
| Eka v7this release | 18 / 103 |
| Eka v9unreleased | 15 / 103 |
| Ampixa Pocket teacherunreleased | 4 / 104 |
Most natural by the predictor, weakest on voice match.
| System | Character error ↓ | Voice match ↑ | UTMOS ↑ |
|---|---|---|---|
| Eka v7this release | 8.8% | 0.52 | 3.24 |
| Eka v9unreleased | 7.5% | 0.48 | 3.33 |
| Swarpublic | 5.6% | 0.69 | 2.67 |
| OmniVoicepublic | 5.0% | 0.70 | 2.63 |
| VoxCPM2public | 9.0% | 0.68 | 2.40 |
| Chatur v5unreleased | 5.4% | 0.67 | 2.79 |
| Audio8 basepublic | 84.5% | 0.34 | 2.73 |
Our harness reproduces Swar's published numbers on this bench. Training exposure of these voices is unknown for every row, so this is not a ranking. UTMOS is an English-trained naturalness predictor, not a listening test.
Where it falls short.
Not the best voice cloner here
Voice match 0.52, the lowest in the table above.
Not the most accurate
OmniVoice, Swar and Chatur all make fewer character errors on the cloning bench.
Not fast on a GPU, not real-time streaming
Slowest family on an L40 GPU (RTF 1.065); on the CPU, 0 of 25 items stayed ahead of playback.
Not ready for older Intel CPUs
On an Intel i5-10400 the INT8 export broke on 11 of the first 12 test sentences. Windows and Linux builds wait for that fix.
Run it yourself.
Eka on Hugging Face
eka-ft-v1 to v9, CPU builds of v7 (onnx/) and v9 (onnx-v9/), and examples/speak.py. Public, no sign-up: ampixa/audio8-nepali.
Astadhwani app
A desktop app for Eka; Mac arm64 preview today. Windows and Linux: आउँदैछ. code
Speak on your CPU
python examples/speak.py --model v9 --text "नमस्ते" --out hello.wav. Add --ref me.wav --ref-text "…" for your own voice. --model v9: fewer word errors; v7: closer voice match.
Receipts and limits
Character error: Naamche cloning bench v1.1 clean track and our bench v1.1 (23 voices outside training), recognizers MMS and our in-house Nepali recognizer. Voice match: ECAPA cosine. UTMOS: SpeechMOS utmos22_strong. Hindi Leak Scorer v84, frozen model 58422b5a. CPU: eka-ft-v7 ONNX, Apple M3 Pro, 4 threads, 39 s paragraph, median of three runs. All are automatic scores; there is no listening panel yet.
Licence: Audio8 Community License v1.0. It bars commercial use at or above US$2M annual revenue and requires consent before cloning a person's voice. Clone only voices you have permission to use.