A phone call is
a different test.
Picture someone in Nepal calling a support line. They need their words written down. A quiet microphone is a different test. NepaliConformer is now Rani.
Speak Nepali. Read it back.
Record or upload up to 60 seconds. It runs on a free CPU, so it may take a minute to wake up. Open full-screen if your microphone is blocked.
Start with the call.
Rani turns spoken Nepali into text. That can help with helplines, captions, voice typing and meeting notes. But a recogniser useful in a quiet room can fail on a call. We tested both. On NepTel, Rani leads the ranked systems shown here without a language model. Each lead has a 95% confidence interval excluding zero. That supports a lead on this sample, not on every call.
The private test uses real Nepali customer-service phone calls: 127 calls Rani never trained on. Rani leads these comparators too. The references are machine-made by Scribe and cannot be checked publicly.
| Rani | 33.5 |
|---|---|
| NepaliConformer offlineour older model | 39.7 |
| AI4Bharat IndicConformer | 47.6 |
Human-corrected references. Every reference was corrected against the audio; the drafting model is unranked. Results and reference provenance.
| Rani | 30.6 |
|---|---|
| AI4Bharat IndicConformer | 38.9 |
| NepaliConformer offlineour older model | 49.2 |
Machine-made Scribe references; not public ground truth. Unseen calls. Each lead has a 95% interval excluding zero. Internal evidence and limits.
against the audio
The answer key is part of the test.
NepTel’s old labels were drafted by Google’s ASR, Chirp 2, then reviewed. In NepTel 0.2, a human listened to and corrected every reference against the audio. A draft can carry its model’s mistakes into the answer key, so the drafting model is not ranked.
Clean speech, and a language model.
Mistakes per 100 letters. Rani with a language model: 3.6 on PVSpeech and 10.4 on FLEURS Nepali. AI4Bharat’s IndicConformer: 9.8 and 7.4.
| Model | PVSpeech | FLEURS |
|---|---|---|
| Rani (language model) | 3.6 | 10.4 |
| AI4Bharat IndicConformer | 9.8 | 7.4 |
PVSpeech: selection set, nonpublic.
Language model not in the released weights. Clean-speech receipts.
How fast does it write?
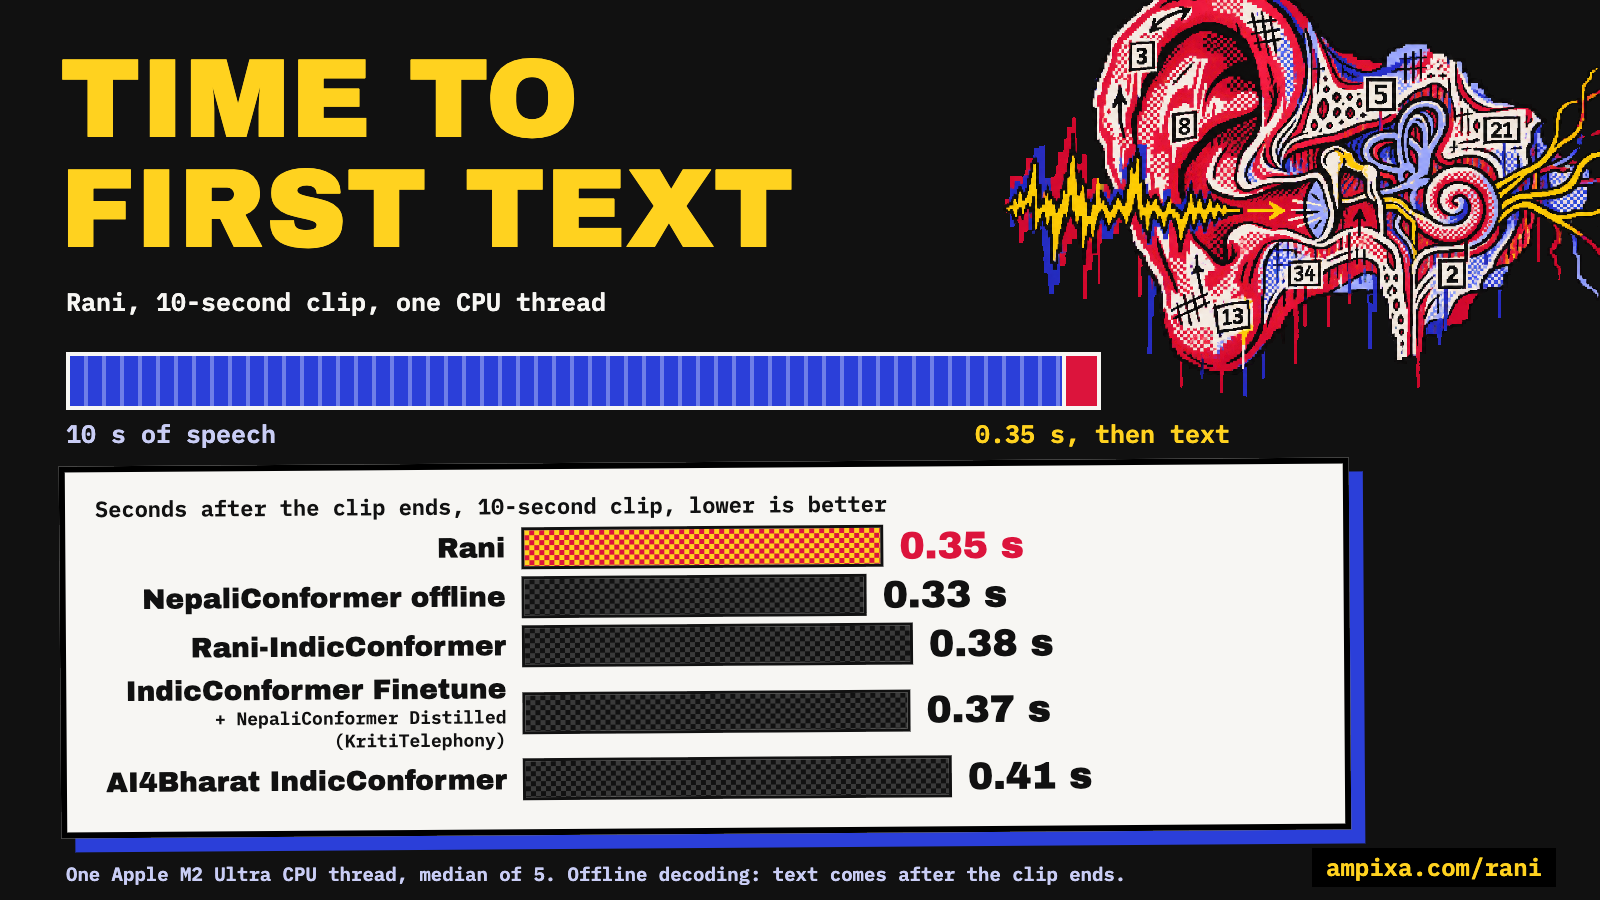
On one CPU thread, Rani transcribes 26.8 times faster than real time. A 10-second clip returns text 0.35 seconds after it ends. It decodes offline, so text arrives when the clip ends, not while you speak.
| Model | × real time | First text, 10 s clip |
|---|---|---|
| Rani | 26.8× | 0.35 s |
| NepaliConformer offline | 27.1× | 0.33 s |
| AI4Bharat IndicConformer | 21.1× | 0.41 s |
| Rani-IndicConformer | 20.8× | 0.38 s |
What changed with the name?
The family has three classes. NepaliConformer offline is the older model. Rani continues that line, trained further for customer calls and read speech. Rani-IndicConformer is a full IndicConformer fine-tune aimed at clean speech. On our internal PVSpeech measurement, it cuts letter errors from IndicConformer’s 9.8 to 3.9 per 100 letters.
- NepaliConformer offline
- The older model.
The public downloads are this earlier work. - Rani
- The continued model line.
Customer calls and read speech. - Rani-IndicConformer
- A full IndicConformer fine-tune.
Clean speech.
The older model’s encoder, which turns sound into useful representations, was initialised from AI4Bharat’s MIT-licensed IndicConformer Nepali encoder. The decoder and Nepali vocabulary are ours, trained on our data. Rani continues this lineage. It uses a TDT decoder, predicting text tokens and their durations, and a Nepali-only vocabulary. The scores measure these choices together, not each choice’s individual benefit.
The next test should be yours.
All flavours in one place.
Approval required to download.
Rani, Rani-IndicConformer and the older NepaliConformer models are together on Hugging Face, and downloading requires approval. Distillers must visibly credit Ampixa Labs in their model card and documentation. The licence also covers training or evaluating another model with our outputs and building or distributing derivatives; the requirement passes onward. Read it before building. Next, use the public NepTel audio and scorer to check your system on the same test. NepTel is for evaluation; don’t train on it.
The number belongs to the test.
Public results link to their source. Private call results are internal measurements and are marked as such.
NepTel 0.2 · 33.5 / 39.7 / 47.6
Rani / old offline / IndicConformer. Word errors per 100 reference words; Rani without a language model. Each lead: 95% interval excludes zero. RESULTS.md, NepTel 0.2.127 unseen calls · 30.6 / 38.9 / 49.2
Rani / IndicConformer / old offline, word errors per 100 words. Each lead: 95% interval excludes zero. This is internal evidence, so the full table and intervals cannot be checked publicly. The references are machine-made by Scribe, and the company overlaps with part of the training data. Repository summary supports the headline comparison; raw private evidence is not public.NepTel 0.1 → 0.2 · key versions
Versions and model identifiers. Old key: Google ASR drafts, then review. Current key: every reference human-corrected against the audio. Reference protocol.Speed · 26.8× / 27.1× / 21.1× / 20.8× · 0.35 / 0.33 / 0.41 / 0.38 s
Rani / NepaliConformer offline / AI4Bharat IndicConformer / Rani-IndicConformer. Greedy transducer decoding on one CPU thread of an Apple M2 Ultra, batch size 1. Speed is over 25 public NepTel clips, 622.72 s of audio. First text is the median of 5 runs on a 10 s clip. Rani and NepaliConformer offline ran on NeMo 3.0.0, the others on NeMo 1.23.0rc0. Measured on a machine also running other work.PVSpeech · 3.6 / 9.8
Rani with language model / IndicConformer. FLEURS · 10.4 / 7.4, same order. The language model is not in the released weights. Letter errors per 100 reference letters. Checkpoint selection influenced; nonpublic. Clean-speech results.Three model classes · 9.8 → 3.9
Rani-IndicConformer versus base IndicConformer on internal PVSpeech, errors per 100 letters, an internal measurement. See the model family. The older model’s encoder started from AI4Bharat’s MIT-licensed IndicConformer encoder; the decoder and vocabulary are ours.Lineage, distillation and release
Architecture; visible credit and pass-through terms. Weights: ampixa/rani-asr, approval required.